Consulting Services

AI Advisory & Implementation

AICON provides expert guidance to build, deploy, and manage AI systems. We turn complex data into clear, actionable business results.

STRATEGIC PLANNING
STRAT-AI-01
READY
AI Roadmap Strategy
Executive-level AI roadmaps aligning model capabilities with business goals to ensure high-impact, scalable enterprise adoption.
Tech Stack:Strategy, Governance, Roadmap, Audit
Use Cases:AI readiness, vendor selection, risk assessment
IMPACT
Projected Efficiency
40% ROI
Expert Advisory
MODEL ENGINEERING
MOD-DEV-02
READY
Proprietary Model Dev
Custom-built LLMs and predictive models trained on your unique data to solve specific industry challenges with precision.
Tech Stack:PyTorch, TensorFlow, LangChain, VectorDB
Use Cases:Domain-specific chat, predictive analytics
IMPACT
Model Precision
98.2%
Expert Advisory
DATA PIPELINES
DATA-PIPE-03
READY
Data Engineering
Robust, secure data infrastructure designed to feed high-quality, cleaned information into your AI models for reliable output.
Tech Stack:Airflow, dbt, Snowflake, Kafka
Use Cases:Real-time ingestion, data cleaning, ETL
IMPACT
Data Throughput
10x Speed
Expert Advisory
AI GOVERNANCE
GOV-COMP-04
READY
Compliance Governance
Frameworks for ethical AI deployment, ensuring your systems meet regulatory standards and internal security requirements.
Tech Stack:Policy, Audit, Security, Ethics
Use Cases:Bias mitigation, data privacy, audit logs
IMPACT
Regulatory Compliance
100% Safe
Expert Advisory
Secure Data Handling
Low Latency Models
Regulatory Aligned
Continuous Monitoring

Expert guidance for your AI journey.

Enterprise Tech Stack

Proven AI infrastructure

Production-tested tooling and compute clusters for enterprise AI.

sub-12ms latency
PyTorch 2.x
v2.3.1 C++ Core

Custom kernels optimized for high-speed attention and memory efficiency.

4.8x scaling
JAX / Flax
XLA JIT Compiled

Compilation pipelines built for massive parallel compute clusters.

94% KV reuse
vLLM Engine
PagedAttention v2

Continuous batching for high-concurrency model serving.

62% savings
TensorRT-LLM
FP8 Quantized

Optimized tensor parallelism for NVIDIA Hopper architectures.

80B+ scale
DeepSpeed
ZeRO-3 Offload

Memory-efficient partitioning for large-scale model training.

99.99% uptime
Hugging Face TGI
Rust Core v2.0

Production-ready token streaming with built-in observability.

Stack Telemetry
Active Nodes:1,240+
Avg Latency:< 24ms
Reliability:99.98%
Enterprise AI Lifecycle

Our Deployment Methodology

We guide your firm from initial discovery to production scaling, ensuring every AI implementation is secure, performant, and aligned with business goals.

Focus:DiscoveryArchitectureImplementationOptimizationMonitoring
Stage 01Technical Protocol

Discovery & Audit

Technical landscape & business goal alignment

We analyze your existing data infrastructure, identify high-impact AI use cases, and define clear success metrics to ensure every deployment drives measurable ROI.

Core Technical Focus

Data quality & pipeline assessment
Infrastructure scalability review
Business process bottleneck mapping
Regulatory & compliance audit
Key Deliverable:

Strategic AI Readiness & Gap Analysis Report
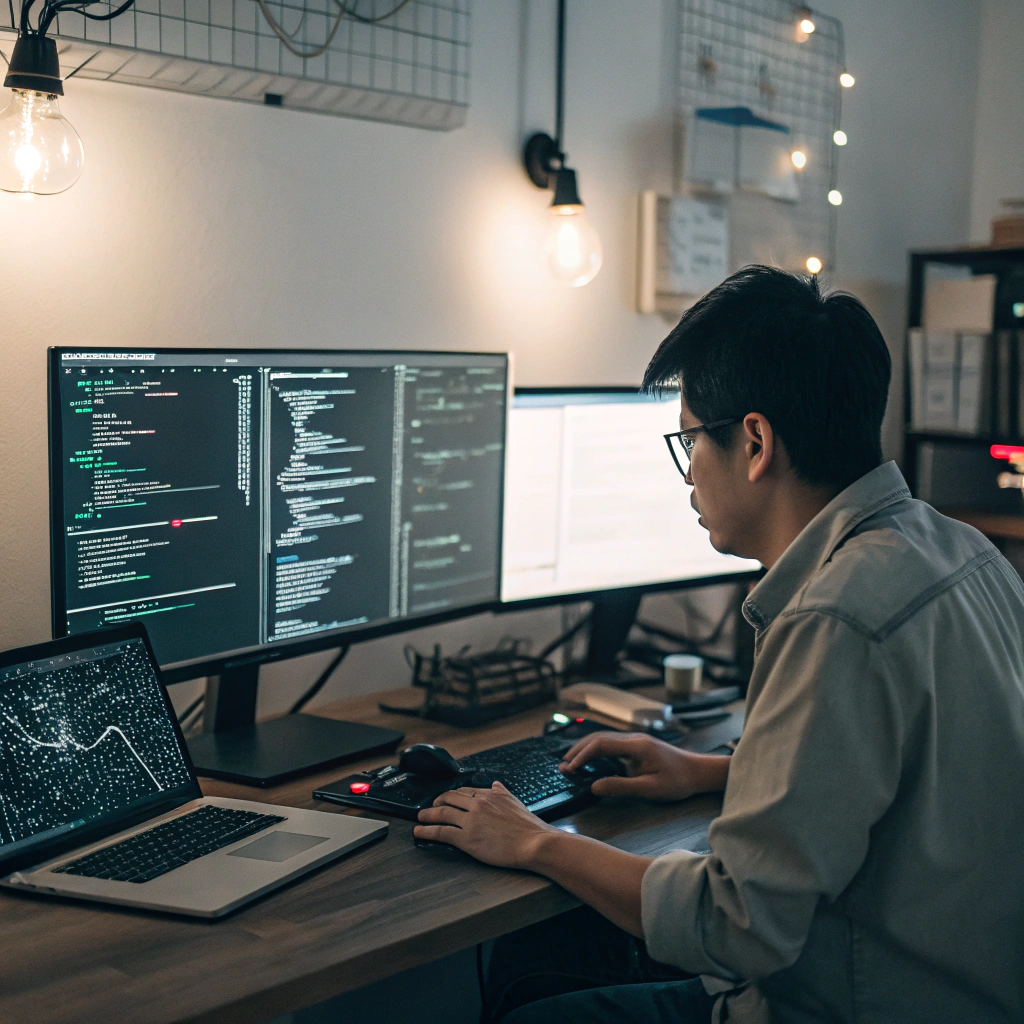
Step 1 of 4
Consultant reviewing technical architecture diagrams on screen

Discovery & Audit

Technical landscape & business goal alignment

Ready to scale your AI capabilities?

Our team of 12 experts is ready to help you build, deploy, and monitor high-impact AI solutions for your enterprise.